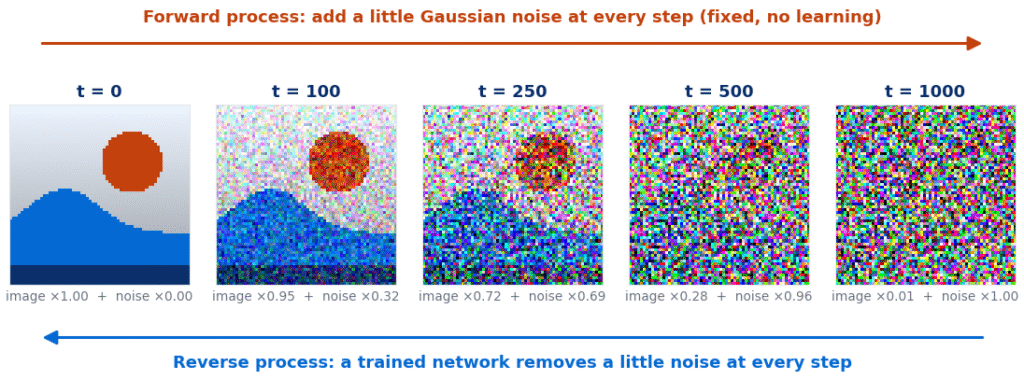
Diffusion Models Explained: How AI Turns Noise Into Images
How diffusion models generate images by learning to reverse step-by-step noising, with text conditioning, why they beat GANs, their cost, and latent diffusion.
Loss functions, activation functions, metrics and the core concepts of how models learn.
How diffusion models generate images by learning to reverse step-by-step noising, with text conditioning, why they beat GANs, their cost, and latent diffusion.
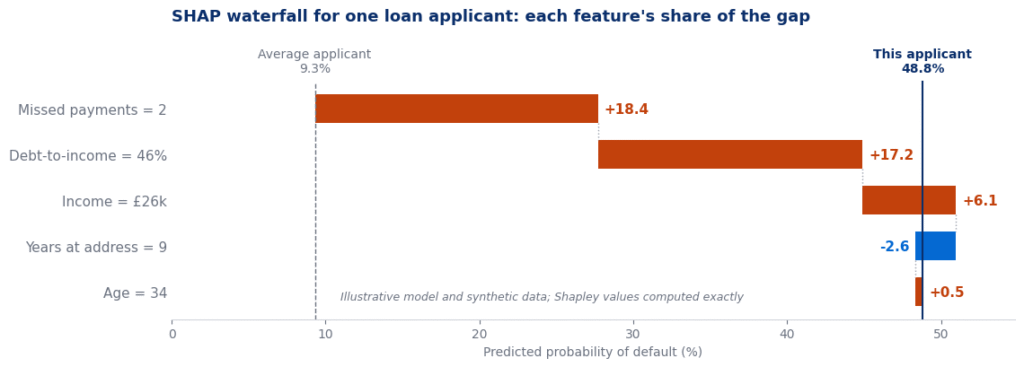
Why explainable AI matters and how SHAP, LIME, partial dependence and feature importance work, with a worked SHAP example and the limits of every explanation.
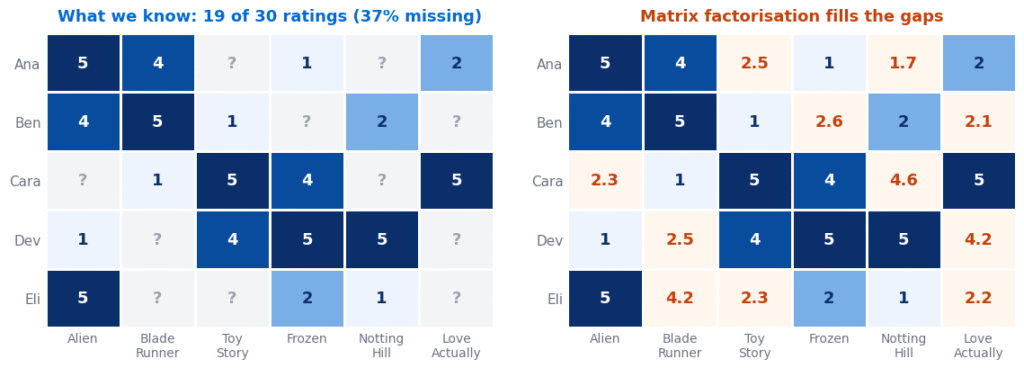
How recommender systems fill in a sparse user-item matrix, from cosine-similarity neighbours to matrix factorisation, plus cold start, popularity bias and implicit feedback.
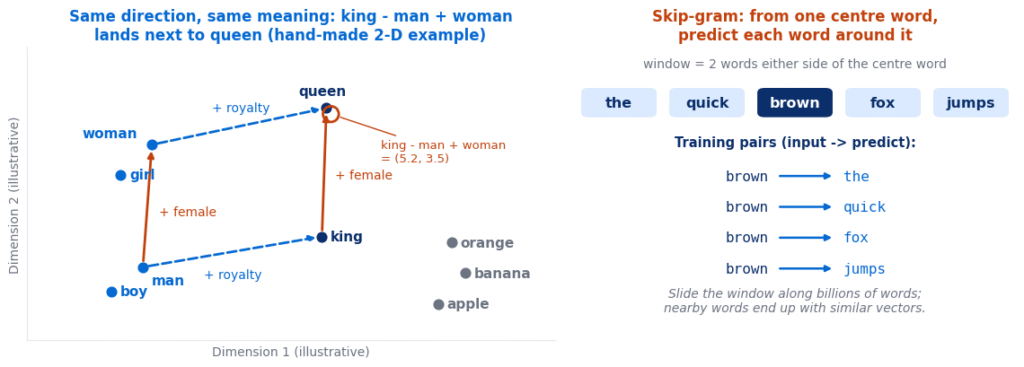
How word2vec learns word vectors from the company words keep, why king – man + woman lands near queen, and where one vector per word falls short.
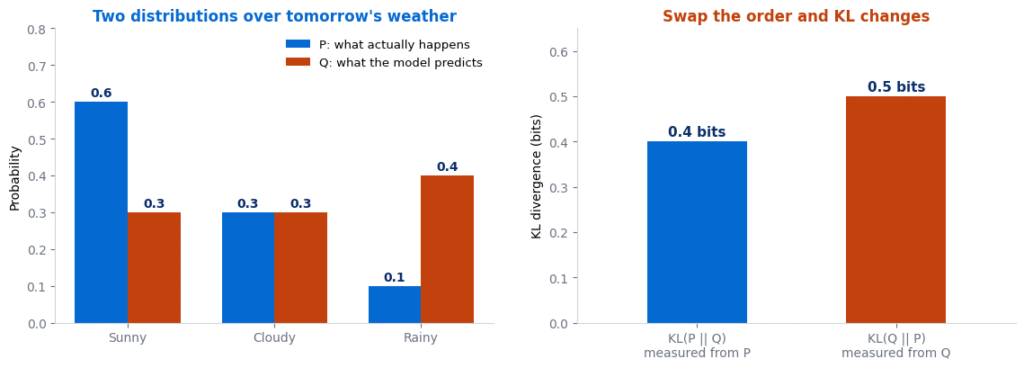
KL divergence explained with a worked example, both directions computed, the cross-entropy link, and where VAEs, distillation and RLHF use it.
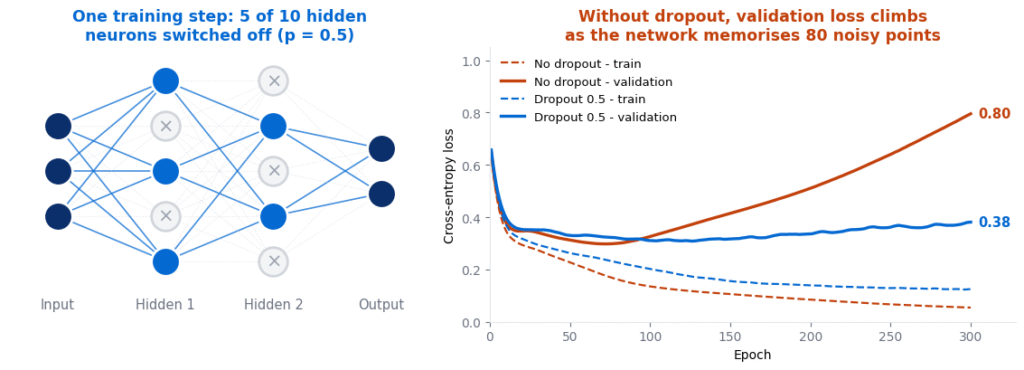
Dropout switches off random neurons while a network trains, which stops overfitting; here is why it works, how the scaling works, and which rates to use.
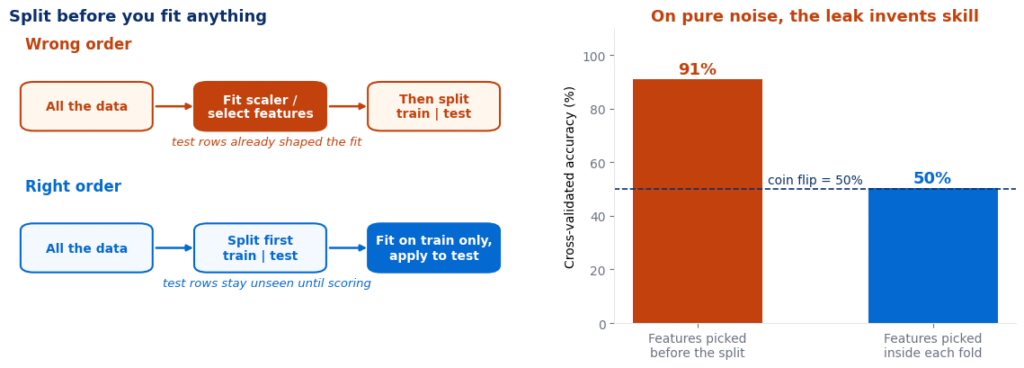
Data leakage lets answers slip into training and inflates your score; learn the five common forms, the warning signs, and why pipelines are the fix.
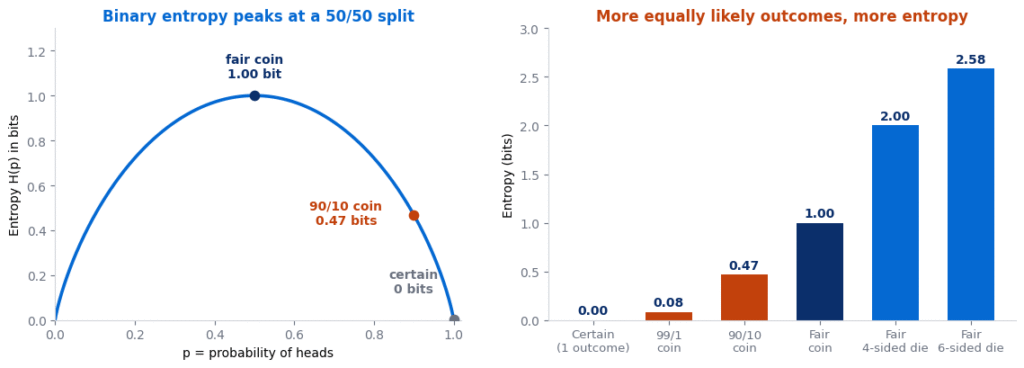
Entropy in machine learning explained through three coins, bits and nats, decision tree information gain and cross-entropy loss.
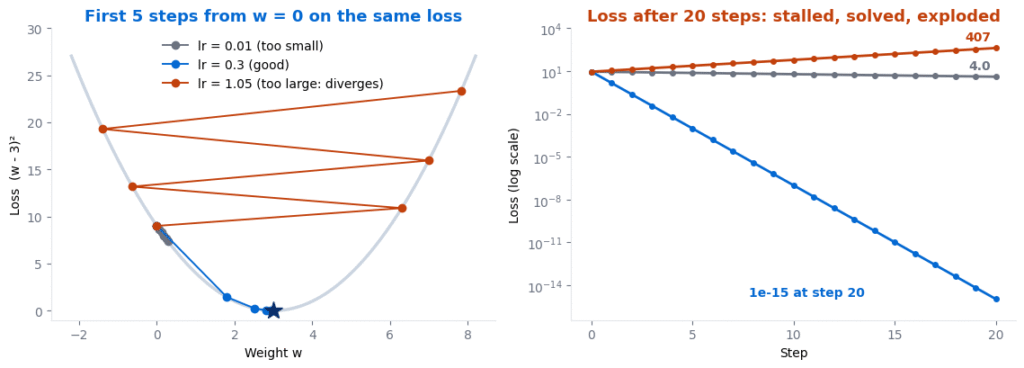
The learning rate sets the size of every training step; see what too small and too large look like, and how to pick one with a range test and a schedule.
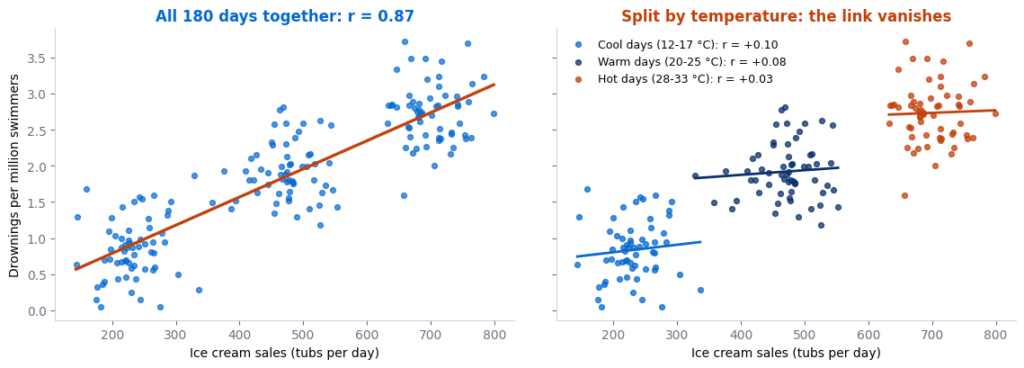
Correlation vs causation explained through confounders, reverse causation, selection bias and chance, and why randomised A/B tests are the fix.