A single decision tree is easy to understand and unfortunately unstable: change a few rows and you get a noticeably different tree. A random forest turns that instability into an advantage.
How a random forest works
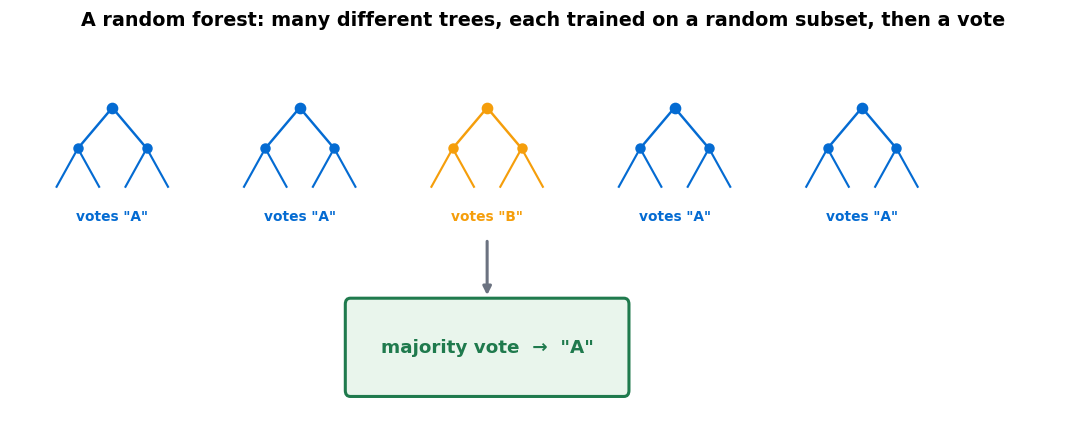
Two sources of randomness, and both are essential:
Random rows (bagging). Each tree trains on a sample drawn with replacement from the training data — same size, but some rows appear twice and roughly a third are left out entirely.
Random features. At every split, each tree may only consider a random subset of the columns. This is the part that makes random forests work rather than merely being an ensemble.
🧪 Why restricting features matters so much
By hiding that feature from most splits, other trees are forced to find different patterns. The trees become genuinely diverse, their errors become uncorrelated, and that is what averaging can cancel out.
Diversity is the mechanism. Without it a forest is just an expensive tree.
Why averaging helps
Each tree overfits its own sample in its own direction — one is fooled by a quirk in rows it saw, another by a different quirk. Those errors are largely independent, so they partly cancel when averaged. What survives is the signal all the trees found, because that was in the data rather than in any one sample.
In the language of the bias–variance tradeoff: individual deep trees are low bias and very high variance. Averaging keeps the low bias and cuts the variance sharply.
Out-of-bag scoring: free validation
Roughly a third of rows are left out of each tree’s training sample. Those rows are “out of bag” for that tree — genuinely unseen — so you can score each tree on its own leftovers and average.
Set oob_score=True and you get a validation estimate without holding anything out or running cross-validation. It is a genuinely useful property that most algorithms do not have.
Settings that matter
| Setting | Effect | Sensible value |
|---|---|---|
n_estimators | Number of trees. More never overfits — it just costs time | 200–500 |
max_features | Columns considered per split — controls diversity | The one worth tuning |
max_depth | Tree depth limit | Often fine unlimited |
min_samples_leaf | Minimum rows per leaf | 1–5 |
Why it is the best default for table data
No scaling needed. Handles mixed types. Copes with irrelevant features. Robust to outliers. Trains in parallel. Rarely overfits badly, and works well without tuning.
For a spreadsheet-shaped problem, a random forest with default settings is a strong baseline that many more sophisticated approaches fail to beat.
The limitations
⚠️ Where random forests fall down
- Interpretability is gone. One tree you can read; 500 you cannot. You get feature importances, not an explanation.
- Feature importance is biased toward high-cardinality columns. Use permutation importance instead.
- Cannot extrapolate. Predictions are averages of training values, so a forest will never predict beyond the range it saw. For a trend that continues upward, use a linear model.
- Large and slow to serve. 500 deep trees is a big model to load and query.
- Weak on images, audio and text — that is neural network territory.
The extrapolation limit surprises people, so it is worth stating plainly: if your training prices top out at £500k, no random forest will ever predict £600k.
🔑 Key Takeaways
- A random forest averages many trees trained on random rows and random features.
- Restricting features per split is what makes the trees diverse — and diversity is the whole mechanism.
- More trees never overfits;
max_featuresis the setting worth tuning. - Out-of-bag scoring gives free validation without a holdout set.
- It cannot extrapolate beyond the range of its training data.
Further reading
scikit-learn’s forest documentation covers bagging, out-of-bag scoring and the tuning parameters, and its permutation importance example shows why the built-in importances mislead.
Where to go next
- Support vector machines — the next algorithm in this sequence
- Decision trees — the building block
- Gradient boosting — trees combined a different way, often more accurate
- Start Here — the full learning path