Fraud, disease screening, equipment failure, click prediction — in the problems that matter most, the thing you are looking for is rare. Imbalanced datasets break the habits every tutorial teaches you, so they are worth understanding before you meet one.
Why accuracy stops working
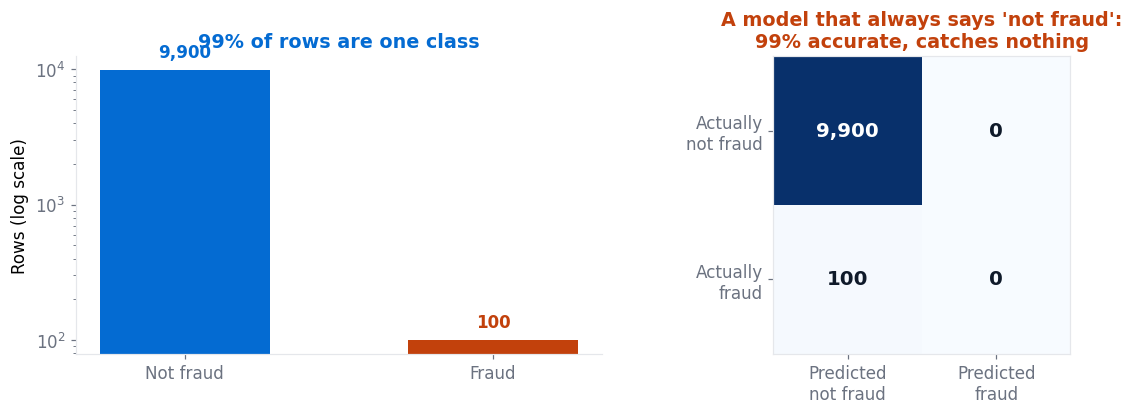
That model is worthless and its headline number is excellent. Worse, ordinary training actively pushes toward it: the loss function is dominated by the 9,900 easy majority cases, so ignoring the rare class is genuinely the easiest way to reduce loss.
Which metric to use
| Metric | Use it when |
|---|---|
| Recall | Missing a positive is expensive — cancer screening, fraud |
| Precision | False alarms are expensive — spam filters, costly interventions |
| F1 score | You need one number balancing both |
| PR-AUC | Severe imbalance. Better than ROC-AUC, which stays flatteringly high because true negatives are abundant |
| Accuracy | Essentially never, on imbalanced data |
Move the threshold before you touch the data
Most classifiers output a probability, then apply a 0.5 cut-off. That default has nothing to recommend it on imbalanced data.
🧪 The cheapest fix there is
Lower the threshold to 0.1 and you catch far more fraud at the cost of more false alarms. Plot precision and recall across thresholds and pick the point that matches what the errors actually cost your business.
This requires no resampling, no new data, and no retraining. Try it before anything else.
Class weights
Most libraries accept class_weight="balanced", which makes errors on the rare class count proportionally more in the loss. One argument, no change to your data, and it is often enough on its own. Try this second.
Resampling, and its risks
Undersampling discards majority examples until the classes balance. Simple and fast, but you are throwing away real data — reasonable only when you have plenty.
Oversampling duplicates minority examples. No data lost, but exact duplicates encourage the model to memorise those specific rows.
SMOTE generates synthetic minority examples by interpolating between real ones and their neighbours, rather than copying. Better than plain duplication, and the usual first choice when resampling.
⚠️ Three ways resampling goes wrong
- Resample the training fold only — never the test set. Balancing before splitting puts synthetic copies of training rows into your test set, and the score becomes fiction. This is the most common and most damaging mistake.
- SMOTE interpolates, so it needs meaningful distances. Scale first, and be careful with one-hot columns, where a synthetic value of 0.6 means nothing.
- Probabilities stop being calibrated. After resampling, a predicted 0.8 no longer means an 80% chance. If you need real probabilities rather than a ranking, prefer class weights.
A sensible order of attack
- Change the metric. Precision, recall, F1, PR-AUC. Costs nothing and reveals the real position.
- Tune the threshold against the actual cost of each error type.
- Try
class_weight="balanced". One argument. - Then try SMOTE or undersampling, inside the cross-validation loop.
- Collect more minority examples if you possibly can — it beats every technique above.
- At extreme ratios — beyond roughly 1 in 1,000 — consider reframing it as anomaly detection rather than classification.
Note that most people jump straight to step 4. Steps 1 to 3 are faster, safer, and frequently sufficient.
🔑 Key Takeaways
- On imbalanced datasets, accuracy rewards a model that ignores the rare class entirely.
- Use precision, recall, F1 or PR-AUC — and read the confusion matrix.
- Adjusting the decision threshold is the cheapest effective fix; try it first.
- Class weights need one argument and often match resampling for results.
- Resample the training fold only, and expect probabilities to lose calibration.
Further reading
The imbalanced-learn library implements SMOTE and the undersampling methods with a scikit-learn compatible pipeline that resamples correctly inside cross-validation, and scikit-learn’s precision-recall example shows why PR curves beat ROC curves when positives are rare.
Where to go next
- The confusion matrix — where to look instead of accuracy
- Precision and recall — the two metrics that matter here
- Bias in machine learning — the same “measure per group” lesson
- Start Here — the full learning path